
What we’re building today
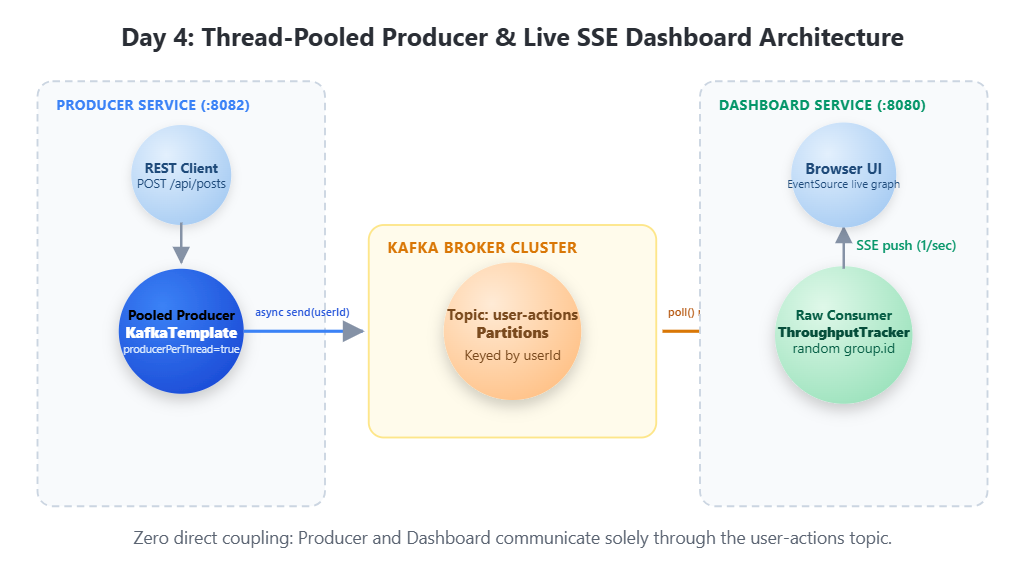
streamsocial-producer-service— a Spring Boot app exposingPOST /api/posts, backed by a pooledKafkaTemplate<String, UserActionEvent>
streamsocial-dashboard— the system’s first browser-visible surface: a live events/sec counter fed by a rawkafka-clientsConsumer, pushed to the page over Server-Sent EventsThe moment where Day 1’s event records and Day 3’s topics stop being things you can only prove with a CLI, and start being things you can watch happen
This is the first lesson where StreamSocial does something a browser can show you. Everything before today built the plumbing; today the plumbing carries real water.
Core concept: a producer is thread-safe, but “thread-safe” isn’t “fast enough”
A single
KafkaProducercan be shared safely across every thread in your app — it’s built for that. But under real concurrent load, that one producer’s internal network client becomes a queue everyone waits behind.DefaultKafkaProducerFactory.setProducerPerThread(true)gives each calling thread its own producer instead, pulled from aThreadLocalpool — that’s what “connection pooling” means for a Kafka producer, distinct from the JDBC sense of the term most engineers learn first.
The other half of today’s concept is what key you send with.
PostProducerServicekeys everyPostCreatedevent byuserId, not randomly or round-robin — because Kafka guarantees ordering only within a partition, and every event for the same user has to land on the same partition to keep that user’s timeline in order. You’ll go deep on this on Day 14; today, just notice it’s already there in the code, on purpose.
Where this fits in StreamSocial
The producer service is the front door: it’s the only thing standing between “a user tapped Post” and a durable fact in Kafka. Everything downstream — Day 5’s engagement consumer, Day 41’s Streams topology, Day 44’s trending scores — depends on this door working correctly and staying open under load, because none of them can process an event that never arrived.
The dashboard, meanwhile, isn’t a side project — it’s the same kind of real-time visibility system StreamSocial’s own engineers would build to answer “is ingestion healthy right now?” without SSH-ing into a broker. It reads
user-actionswith a plainKafkaConsumeron a fresh, randomgroup.idevery time it starts, subscribed fromlatest— a monitoring consumer has no business replaying history, it only cares what’s happening now.
Architecture: request in, fact out, dashboard watching
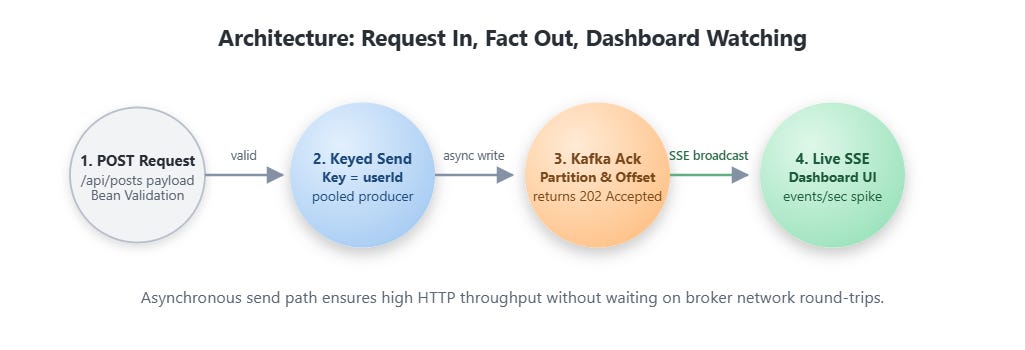
A POST /api/posts becomes a PostCreated event, gets validated by the same Bean Validation constraints Day 1 defined, and is handed to the pooled KafkaTemplate. The send is asynchronous — the HTTP response doesn’t block on the broker round-trip, it completes when Kafka acknowledges the write and returns the real partition and offset the event landed on.
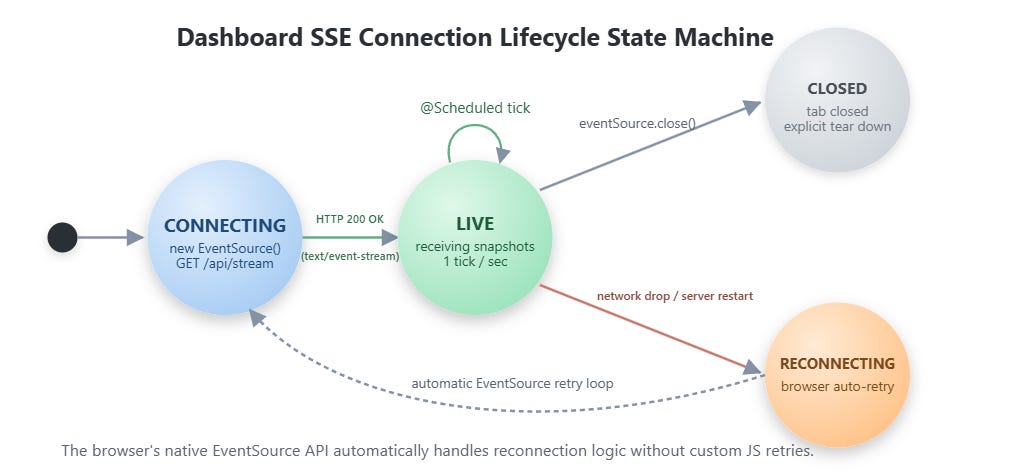
The dashboard’s browser connection has its own lifecycle, independent of any single event: it opens an EventSource, sits in a live state receiving a JSON snapshot every second from the server’s @Scheduled broadcaster, and silently reconnects if the connection drops — the browser’s EventSource API does that retry for you, no extra code required.
Implementation Guide :
GitHub Link :
https://github.com/sysdr/streamsocial-java/tree/main/streamsocial-day04/streamsocial
Fundamentals first
KafkaProducer batches records internally and manages its own background I/O thread — that’s why it’s thread-safe to share. The pooling question isn’t “is one producer safe to share,” it’s “does sharing it become a bottleneck before your network or the broker does.” At real scale, the answer is often yes, which is why Day 4’s pattern exists at all.
Today’s specific pattern: producer-per-thread + async send
Pseudo-code shape of the pooling config:
ProducerFactory<String, UserActionEvent> factory = new DefaultKafkaProducerFactory(props)
factory.setProducerPerThread(true)   // each thread gets its own pooled producer, not one shared instance
KafkaTemplate template = new KafkaTemplate(factory)
And the send path itself, keyed and async:
event = new PostCreated(eventId, now, userId, postId, content)
template.send(topic="user-actions", key=event.userId(), value=event)
    .thenApply(result -> respond 202 with result.partition(), result.offset())
Nothing here blocks the HTTP thread on the broker round-trip — the CompletableFuture completes when Kafka acknowledges the write, and the controller maps that into the HTTP response.
How it snaps into the system
streamsocial-producer-service imports PostCreated/UserActionEvent from streamsocial-common (Day 1) — it does not redefine them. It sends to user-actions, the exact topic Day 3’s TopicBootstrap created — it does not create its own topic. streamsocial-dashboard reads that same topic independently, with its own consumer group, so producer and dashboard have zero direct coupling to each other — only to the topic between them.
Build, test, and demo — step by step
1. Unit tests (no broker needed)
cd streamsocial
mvn -pl streamsocial-producer-service,streamsocial-dashboard -am test
Expected: CreatePostRequestValidationTest (3 tests) and ThroughputTrackerTest (2 tests) pass — these test validation and the throughput-counting logic in isolation.
2. Integration test (real broker via Testcontainers)
mvn -pl streamsocial-producer-service -am verifyExpected: PostProducerServiceIT spins up a real Kafka container, sends a real event, and reads it back with a real consumer. On a standard Docker host or CI runner this passes outright. If your sandbox’s Docker bridge doesn’t expose a Testcontainers-compatible API (some WSL2 + Docker Desktop setups don’t), start.sh detects that specific failure and falls back to manual verification against the already-running cluster instead of halting — check its output for which path actually ran.
3. Full lifecycle, with Docker
./start.shExpected: cluster up, topics bootstrapped (12/6 partitions locally — production default is 1000/500, see below), both services healthy, 5 real posts sent, and a live SSE snapshot printed showing totalEvents reflecting them.
4. Manual verification
curl -X POST localhost:8082/api/posts \
  -H "Content-Type: application/json" \
  -d '{"userId":"<any-uuid>","content":"hello StreamSocial"}'
Expected: 202 Accepted with a real partition and offset.
Open http://localhost:8080 and watch the events/sec number spike the instant you send another one.
5. No-Docker note
The producer and dashboard are plain Spring Boot apps — mvn -pl streamsocial-producer-service spring-boot:run works without Docker for compiling/starting the JVM process itself, but both need a real broker to do anything useful, so Docker (or a broker reachable some other way) is required for this lesson’s actual demo, unlike Day 1.
6. Shut down
./stop.shExpected: both apps and all three brokers stop cleanly; safe to re-run start.sh immediately after.
The local-scale vs. production-scale gap
The Day 4 challenge target is 5M posts/second. This lesson’s code doesn’t pretend to hit that on a laptop against a 3-broker local cluster — that number comes from partitioning (1000 partitions on user-actions, per Day 3) and running across a real horizontally-scaled cluster, not from any one producer’s configuration. What today’s code proves is the mechanism — pooling, async sends, correct keying — at a scale your machine can actually run in seconds.
Success criterion
Run ./start.sh. It will bring up the 3-broker cluster, bootstrap topics, start both new services, fire 5 real posts through the producer, and print a live snapshot from the dashboard’s own SSE stream — you should see totalEvents in that snapshot match what was just posted. Then open http://localhost:8080 yourself, curl -X POST localhost:8082/api/posts a few more times by hand, and watch the number move in real time. If you can explain why the dashboard’s consumer never commits an offset, you’ve got today’s concept.
Working Demo Link :
Homework assignment
Add a
PostProducerThroughputTest(JUnit, real broker via Testcontainers) that sends 1,000 events in a tight loop across multiple threads and asserts it completes in under 5 seconds — a real, if modest, throughput floor.Change the dashboard’s sparkline window from 30 seconds to 60, and confirm
ThroughputTrackerTest‘s history-cap test still passes after you update its expected size.Add a second dashboard panel: total events per partition (not just total), using the same
ConsumerRecord.partition()you already have access to in the poll loop.
Solution hints
For the throughput test, submit sends from an
ExecutorServicewith several threads andCompletableFuture.allOf(...).get()to wait for all of them — this is exactly what exercisessetProducerPerThread(true).ThroughputTracker‘sHISTORY_SIZEconstant is the only thing that needs to change for the 60-second window; the deque logic already handles any size.Per-partition counts need a
Map<Integer, AtomicLong>insideThroughputTrackerrather than a single counter — keyed byrecord.partition()from the consumer, broadcast the same way as the existing snapshot.